✷ Maker
Giving my robot reflexes: a 0.8B model, 200 ms, no waiting for the LLM
For the $4 toy robot from my last post, understanding "back up" meant a full round trip through speech-to-text, a chat model and text-to-speech. This post is about the 0.8B model I put in front of the chat model: trained for half an hour on free Colab, running on a Mac mini, it turns a simple spoken command into a move in about 200 ms. It also covers why a model with only 86.6% accuracy is safe to use, and why the robot's brain moved from the phone to a computer.
First, the video. I said "back up", and the robot backed up right away — too fast. The phone on its back is heavy, the center of gravity shifted, and the whole thing went over.
That was a real crash, and I'll come back to what it changed. But look at how fast it moved first: between the end of my sentence and the robot moving, nothing waited on the LLM.
1. "Stop" took a round trip
As I wrote in the last post, every sentence goes the same way: the microphone records, speech-to-text turns it into words, the chat model decides what to say and do, text-to-speech reads the answer out, and the moves go to the motor.
For conversation, that round trip is fine. You ask it a science question and wait a couple of seconds for the answer. That feels natural.
Driving is different. By the time you say "stop", the car is already moving. If it has to wait for the chat model to finish thinking, it has already hit the table leg.
Last time my answer was a stop word: a keyword spotter on the phone heard "all stop" and braked at once, without asking the LLM. I have since removed it, for three reasons:
- An English phrase is unfriendly to Chinese speakers. I added a line spelling it in pinyin, and in testing it never fired once.
- The robot talks too. I had to tell the chat model in its prompt never to say "all stop", or it would brake itself the moment it opened its mouth.
- Now that the project is open source, most people don't connect it to a car that drives. They run a character that only talks.
Today the brake is the stop button on the screen. But I still wanted something that understands speech and doesn't wait for the LLM. And it shouldn't know just one fixed phrase: "stop", "stop there", "hold it", "okay, that's enough" should all count.
2. Decision models answer multiple choice, they don't write
The last post ended with the "reflex layer": when my kid barked at the robot, a decision model called JEV first judged whether that was teasing, and if so the robot barked back without involving the chat model.
A decision model is not a chat model. You give it a piece of "state" (what the robot last said, what the person just said) and a multiple-choice question. It doesn't write a word; it just tells you the probability of each answer. With no text to generate token by token, it is fast.
Then Unsloth published a guide, Train your own decision model with Unsloth. After reading it I thought: if it can tell a bark from a reply, why not simple commands?
So I gave it this question:
A person is talking to a small wheeled robot. Is the person telling the robot to make one simple move it can carry out right away?
There are seven answers: stop, forward (a little), backward (a little), left, right, keep_going (drive forward until told to stop), and pass: not a simple command, so let the chat model think about it.
3. The data: when unsure, pass
The data took the most care, and within the data, pass took the most.
The two kinds of mistake cost very different things. Taking chat for a command makes the car lurch off. Taking a command for chat only hands it to the chat model, which is a little slower. So pass is deliberately the largest class, with a set of lines that look like commands but aren't:
| Person said | Answer |
|---|---|
| I can't stop laughing | pass: an idiom with "stop" in it |
| i turned left at the light today | pass: a story, not a command |
| Do you ever get tired of driving? | pass: a question |
| okay turn around | pass: more than one simple move |
| hey go forward ten seconds | pass: an exact duration, for the chat model |
| Turn the TV on | pass: not meant for the robot |
Some lines depend on what the robot just said. If the robot asks "Should I come over?" and you say "hey come here", that's forward. If it asks "Left or right?" and you say "Left.", that's left. So every row carries the robot's last line, just as at run time. Most of the time that line has nothing to do with the command, and some mention "stop" or "left" on purpose, so the model learns not to be led by it.
I didn't write these phrases one by one. I distilled them with Claude Code: I spelled out the rules — what each of the seven answers means, that pass should dominate, which kinds of hard negatives to cover — and had it write a large bank of English phrases. A script then makes variants of each one: lower case, no punctuation, a leading "um" or "hey robot". That gave 490 training rows and 164 test rows. The split is by base phrase, so every variant of a phrase lands on the same side. Otherwise the test set would be full of training sentences with different capitalization, and the score would be inflated.
The dataset is on Hugging Face: beasaltfish/robot-simple-commands.
4. Training on Colab: half an hour, free
Training followed Unsloth's guide. There was nothing to invent:
- Base model: Qwen3.5-0.8B.
- LoRA fine-tuning with Unsloth's
FastDecisionModel, rank 16, learning rate 2e-4. - 60 steps, about 4 epochs.
- Merged to 16-bit weights afterwards, plus a GGUF export.
The whole run took about half an hour on a free Google Colab GPU and cost nothing.
Test accuracy is 86.6%, 142 of 164. The model is public too: beasaltfish/robot-simple-commands-qwen3.5-0.8b (and a GGUF version).
5. Why 86.6% is enough
86.6% doesn't sound high: one sentence in seven or eight is wrong. But where it is wrong matters more than how often.
A decision model gives probabilities. My rule is that a move only happens if its probability is above 0.8. Anything else counts as pass and goes to the chat model. So the sentences the model is unsure about never become moves at all. They just take the slower path.
And since pass dominates the data, when the model is wrong it tends to be wrong toward "don't move". On the real car it works much better than 86.6% suggests. That is exactly what I wanted: a reflex can be late, but it must not be wrong.
6. Wiring it into the robot
The model runs on a Mac mini M4 at home, under Unsloth Studio. Point it at the model when starting it, and it serves a /v1/systemone endpoint on the local network:
UNSLOTH_SYSTEMONE_MODEL=~/.cache/huggingface/hub/models--beasaltfish--robot-simple-commands-qwen3.5-0.8b/snapshots/… \
  unsloth studio -H 0.0.0.0 -p 8888
For every sentence the robot's brain hears, before asking the chat model, it sends the sentence and the robot's last line to that endpoint:
- A move above 0.8 is carried out at once. Forward, backward, left and right each drive for 0.6 s; stop stops; "keep going" drives until you say stop. This turn makes no sound, only the move.
- Nothing above 0.8, or the answer is
pass: the chat model gets the turn as usual. - An error, a timeout (1.5 s), or Studio not running at all: the chat model gets the turn as usual. The reflex is a shortcut, and when the shortcut is down the robot still has to answer.
One small detail: after a reflex moves the robot, the chat model's history gets a note: [Before you could think, your reflexes answered: move backward/straight 600ms]. Otherwise, when you ask "why did you back off so fast?", it would have no idea what you mean.
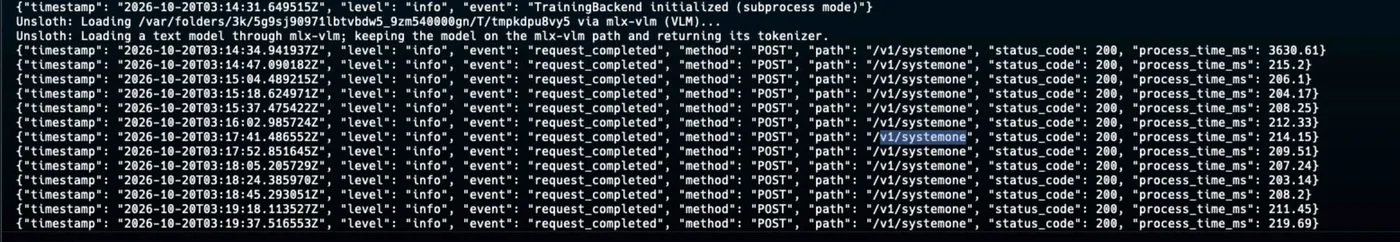
This is the server log from when the video was recorded. The first request loads the model into memory and takes 3.6 s; every request after that takes between 203 and 220 ms. Those 200 ms run from receiving the transcript to choosing a move, and don't include speech-to-text itself.
The question, and what each answer does, aren't hard-coded. They are data. The admin page comes with two presets: "bark" from the last post, and this post's "simple commands". Copy one in and change whatever you like: a different question, another answer, or a left turn of 1 s instead of 0.6.
7. Why the brain moved from the phone to a computer
If you read the last post, you'll notice something changed. Back then the robot was all phone: voice detection ran in the phone's browser, which called the cloud services itself. The brain lived in the phone.
Now the brain is a Node server on a computer. The phone is just the body: it listens, plays sound, drives and shows a face. Each robot is a "character" with its own name, voice, providers and keys, all set up on an admin page in the computer's browser. The phone scans a QR code and becomes that character's body.
There were two reasons for the move.
The first is running locally. Everything that hears and understands you can, over time, run on your own machine and never leave the house. The reflex model already does: it runs on the Mac mini without calling any cloud service. Speech-to-text, the chat model and text-to-speech still go to cloud APIs for now, and will come home one at a time.
The second is a different body. With the brain out of the phone, the body can be anything that can listen, play sound and drive a motor — an ESP32 board that costs a few dollars, for example. The crash at the top of this post is the best argument for that: a phone is simply too heavy for this little car. The ESP32 firmware is written but not yet on the car.
Both deserve a post of their own, so that's for next time.
Want to try it?
- Code: github.com/beasaltfish/bot-reborn, MIT licensed. The scripts that build the data are in
training/commands/. - Dataset: beasaltfish/robot-simple-commands
- Model: beasaltfish/robot-simple-commands-qwen3.5-0.8b
- Training method: Train your own decision model with Unsloth
- Video: watch it on YouTube
No car? Set the character's body to "Cannot move" on the admin page, and an old Android phone plus a computer make a character you can talk to.
Thanks to Unsloth for laying out the decision-model training so clearly. All I did was follow it with a different question.